Showing posts with label API. Show all posts

Sunday, August 3, 2025

FastAPI and Flask Docker Space on Hugging Face

Follow these steps to get started (or read the full documentation)

Start by cloning this repo by using:

Use an access token

# When prompted for a password, use an access token with write permissions.
# Generate one from your settings: https://huggingface.co/settings/tokens
git clone https://huggingface.co/spaces/Nasma/fastapi
# Make sure hf CLI is installed: pip install -U "huggingface_hub[cli]"
hf download Nasma/fastapi --repo-type=space

Create a simple Python app using FastAPI:

requirements.txt

fastapi
uvicorn[standard]
Hint You can also create the requirements file file directly in your browser.

app.py

from fastapi import FastAPI

app = FastAPI()

@app.get("/")
def greet_json():
    return {"Hello": "World!"}
or with Flask
import flask
# instantiate flask
app = flask.Flask(__name__)
# homepage
@app.route("/", methods=["GET","POST"])
def homepage():
return flask.render_template("index.html")
if __name__ == "__main__":
    app.run(debug=True)
Index.html
<!DOCTYPE html>
<html lang="en">
<head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title>{{ data.title }}</title>
</head>
<body>
    <h1>{{ data.message }}</h1>
</body>
</html>

 
Hint You can also create the app file file directly in your browser.

Create your Dockerfile:

# Read the doc: https://huggingface.co/docs/hub/spaces-sdks-docker
# you will also find guides on how best to write your Dockerfile

FROM python:3.10

RUN useradd -m -u 1000 user
USER user
ENV PATH="/home/user/.local/bin:$PATH"

WORKDIR /app

COPY --chown=user ./requirements.txt requirements.txt
RUN pip install --no-cache-dir --upgrade -r requirements.txt

COPY --chown=user . /app
CMD ["uvicorn", "app:app", "--host", "0.0.0.0", "--port", "7860"]
Hint Alternatively, you can create the Dockerfile file directly in your browser.

Then commit and push:

git add requirements.txt app.py Dockerfile			
git commit -m "Add application file"
git push

Finally, your Space should be running on this page after a few moments!

App port

Your Docker Space needs to listen on port 7860.

Personalize your Space

Make your Space stand out by customizing its emoji, colors, and description by editing metadata in its README.md file.

Documentation

Read the full documentation for Docker Spaces here.


Monday, March 10, 2025

Run Gemini Nano Locally in Google Chrome

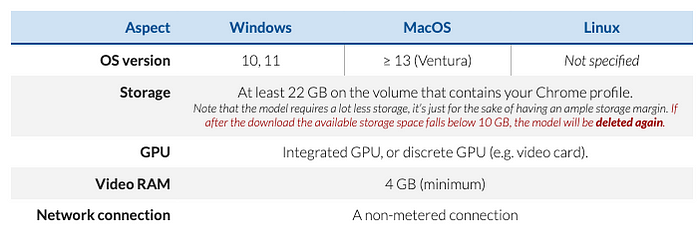
 Running Gemini Nano in Google Chrome doesn't require any data network.

Requirements

A "desktop platform" with

  • Recent operating system (OS) version
  • 22+ GB on the volume that contains your Chrome profile.
  • GPU
  • 4 GB Video RAM
Requirements for Gemini Nano in Google Chrome

Download Google Chrome for Developers

To run Gemini Nano in Google Chrome you will have to download a special version of Google Chrome — Google Chrome for developers / Canary.

Download Google Chrome for Developers from Dev channel (or Canary channel), version at least 128.0.6545.0.

Check the version by typing chrome://version it into the URL bar and pressing Enter.

Enable Feature Flags & Check For Updates

Enable two feature flags :

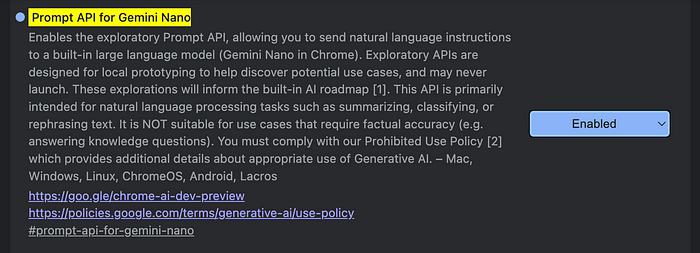
  1. Prompt API — To send natural language instructions to an instance of Gemini Nano in Chrome.
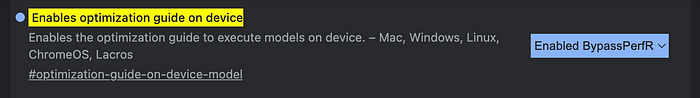
  2. On-device model — To bypass performance checks that might get in the way of downloading Gemini Nano on your device.

On-device model Flag

Open a new tab in Chrome, go to chrome://flags/#optimization-guide-on-device-model

Select Enabled BypassPerfRequirement to facilitate a smooth download of Gemini Nano on your laptop.

None

Relaunch Google Chrome for Developers.

Prompt API Flag

Open a new tab in Chrome, go to chrome://flags/#prompt-api-for-gemini-nano to Enabled.

None

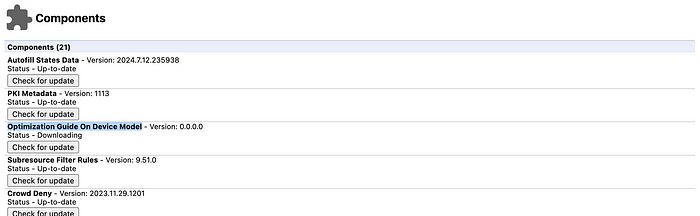
If you do not see "Optimization Guide On Device Model" listed, you may need to wait 1–2 days before it shows up (this was the case for me).

Relaunch Google Chrome for Developers.

Check For Updates

At this point, it's good to check for updates. As said above, this is an experimental feature and might change over time even with short notice.

Go to chrome://components and click "Check for Update" on "Optimization Guide On Device Model"

None

The version should be greater or equal to 2024.5.21.1031.

If you do not see "Optimization Guide On Device Model" listed, you may need to wait a few minutes or some hours (this was the case for me).

Once the model has downloaded go to the next step: Run Gemini Nano in Google Chrome.

Run Gemini Nano in Google Chrome

To verify that everything is working correctly, open the browser console e.g. DevTools (Shift + CTRL + J on Windows/Linux or Option + ⌘ + J on macOS) and run the following code:

(await ai.languageModel.capabilities()).available;

If this returns "readily", then you are all set.

If it fails, we need to force Chrome to recognize that we want to use this API.

So, from the same console send the following code:

await ai.languageModel.create();

This will likely fail but apparently it's intended.

Relaunch Google Chrome for Developers.

Then go through the Check For Updates section again.

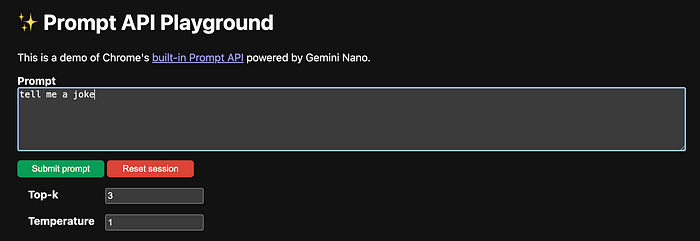
Use Gemini Nano With UI

At this point, you are ready to try the built-in version of Gemini Nano on Chrome for developers!

You can find an intuitive UI using the Chrome Dev Playground.

Chrome Dev Playground.

Use Gemini Nano APIs

Try out the API by simply using it in the browser console.

Start by checking if it's possible to create a session based on the availability of the model, and the characteristics of the device.

In the browser console, run:

const {available, defaultTemperature, defaultTopK, maxTopK } = await ai.languageModel.capabilities();

if (available !== "no") {
  const session = await ai.languageModel.create();

  // Prompt the model and wait for the whole result to come back.  
  const result = await session.prompt("Tell me a German joke");
  console.log(result);
}

Built-in AI models guarantee certain benefits over using models online:

  • Virtually Zero Costs
  • Faster Response Time
  • Offline availability
  • Local processing of sensitive data

This early preview of Gemini Nano allows text interactions. Naturally, the quality of the output does not match the quality of bigger LLM models...

The core object is window.ai. It has three core methods:

  • canCreateTextSession
  • createTextSession
  • textModelInfo

If you first check for window.ai, you could then use canCreateTextSession to see if AI support is really ready, if it iss on a supported browser and the model has been loaded. This does not return true, but... readily.

textModelInfo returns information about the model:

{
    "defaultTemperature": 0.800000011920929,
    "defaultTopK": 3,
    "maxTopK": 128
}
Finally: createTextSession.
const model = await window.ai.createTextSession();
await model.prompt("Who are you?"); 
promptStreaming method is for working with a streamed response.
Example: 
<script defer src="https://cdn.jsdelivr.net/npm/alpinejs@3.x.x/dist/cdn.min.js"></script>

<h2>window.ai demo</h2>

<div x-data="app">
	<div x-show="!hasAI">
		Sorry, no AI for you. Have a nice day.
	</div>
	<div x-show="hasAI">
		<div class="row">
			<div class="column">
				<label for="prompt">Prompt: </label>
			</div>
			<div class="column column-90">
			<input type="text" x-model="prompt" id="prompt">
			</div>
		</div>
		<button @click="testPrompt">Test</button>
		<p x-html="result"></p>
	</div>
</div> 
document.addEventListener('alpine:init', () => {
  Alpine.data('app', () => ({
		hasAI:false,
		prompt:"",
		result:"",
		session:null,
		async init() {
			if(window.ai) {
				let ready = await window.ai.canCreateTextSession();
				if(ready === 'readily') this.hasAI = true;
				else alert('Browser has AI, but not ready.');
				this.session = await window.ai.createTextSession();
			}
		},
		async testPrompt() {
			if(this.prompt === '') return;
			console.log(`test ${this.prompt}`);
			this.result = '<i>Working...</i>';
			try {
				this.result = await this.session.prompt(this.prompt);
			} catch(e) {
				console.log('window.ai error', e);
			}
		}
  }))
}); 
Text summarization:
<script defer src="https://cdn.jsdelivr.net/npm/alpinejs@3.x.x/dist/cdn.min.js"></script>

<h2>window.ai demo</h2>

<div x-data="app">
  <div x-show="!hasAI">
    Sorry, no AI for you. Have a nice day.
  </div>
  <div x-show="hasAI">
    <p>
      <label for="inputText">Enter the text you would like summarized below:</label>
      <textarea x-model="inputText" id="inputText"></textarea>
    </p>

    <button @click="testSummarize">Summarize</button>
    <p x-html="result"></p>
  </div>
</div>
 document.addEventListener('alpine:init', () => {
  Alpine.data('app', () => ({
    hasAI:false,
    inputText:"",
    result:"",
    session:null,
    async init() {
      if(window.ai) {
        let ready = await window.ai.canCreateTextSession();
        if(ready === 'readily') this.hasAI = true;
        else alert('Browser has AI, but not ready.');
        this.session = await window.ai.createTextSession();
      }
    },
    async testSummarize() {
      if(this.inputText === '') return;
      this.result = '<i>Working...</i>';
      try {
        let prompt = `Summarize the following text:
        
${this.inputText}`;
        this.result = await this.session.prompt(prompt);
      } catch(e) {
        console.log('window.ai error', e);
      }
    }
  }))
});
-------
const session = await ai.languageModel.create();

// Prompt the model and wait for the whole result to come back.
const result = await session.prompt("Write me a poem.");
console.log(result);

// Prompt the model and stream the result:
const stream = await session.promptStreaming("Write me an extra-long poem.");
for await (const chunk of stream) {
console.log(chunk);
} 

System prompts

The language model can be configured with a special "system prompt" which gives it the context for future interactions:
const session = await ai.languageModel.create({
  systemPrompt: "Pretend to be an eloquent hamster."
});

console.log(await session.prompt("What is your favorite food?"));

The system prompt is special, in that the language model will not respond to it, and it will be preserved even if the context window otherwise overflows due to too many calls to prompt().

If the system prompt is too large, then the promise will be rejected with a QuotaExceededError exception.

N-shot prompting

If developers want to provide examples of the user/assistant interaction, they can use the initialPrompts array. This aligns with the common "chat completions API" format of { role, content } pairs, including a "system" role which can be used instead of the systemPrompt option shown above.

 const session = await ai.languageModel.create({
  initialPrompts: [
    { role: "system", content: "Predict up to 5 emojis as a response to a comment. Output emojis, comma-separated." },
    { role: "user", content: "This is amazing!" },
    { role: "assistant", content: "❤️, ➕" },
    { role: "user", content: "LGTM" },
    { role: "assistant", content: "👍, 🚢" }
  ]
});

// Clone an existing session for efficiency, instead of recreating one each time.
async function predictEmoji(comment) {
  const freshSession = await session.clone();
  return await freshSession.prompt(comment);
}

const result1 = await predictEmoji("Back to the drawing board");

const result2 = await predictEmoji("This code is so good you should get promoted");

(Note that merely creating a session does not cause any new responses from the language model. We need to call prompt() or promptStreaming() to get a response.)

Some details on error cases:

  • Using both systemPrompt and a { role: "system" } prompt in initialPrompts, or using multiple { role: "system" } prompts, or placing the { role: "system" } prompt anywhere besides at the 0th position in initialPrompts, will reject with a TypeError.
  • If the combined token length of all the initial prompts (including the separate systemPrompt, if provided) is too large, then the promise will be rejected with a QuotaExceededError exception.

Customizing the role per prompt

Our examples so far have provided prompt() and promptStreaming() with a single string. Such cases assume messages will come from the user role. These methods can also take in objects in the { role, content } format, or arrays of such objects, in case you want to provide multiple user or assistant messages before getting another assistant message:

 const multiUserSession = await ai.languageModel.create({
  systemPrompt: "You are a mediator in a discussion between two departments."
});

const result = await multiUserSession.prompt([
  { role: "user", content: "Marketing: We need more budget for advertising campaigns." },
  { role: "user", content: "Finance: We need to cut costs and advertising is on the list." },
  { role: "assistant", content: "Let's explore a compromise that satisfies both departments." }
]);

// `result` will contain a compromise proposal from the assistant.

Emulating tool use or function-calling via assistant-role prompts

A special case of the above is using the assistant role to emulate tool use or function-calling, by marking a response as coming from the assistant side of the conversation:

 const session = await ai.languageModel.create({
  systemPrompt: `
    You are a helpful assistant. You have access to the following tools:
    - calculator: A calculator. To use it, write "CALCULATOR: <expression>" where <expression> is a valid mathematical expression.
  `
});

async function promptWithCalculator(prompt) {
  const result = await session.prompt(prompt);

  // Check if the assistant wants to use the calculator tool.
  const match = /^CALCULATOR: (.*)$/.exec(result);
  if (match) {
    const expression = match[1];
    const mathResult = evaluateMathExpression(expression);

    // Add the result to the session so it's in context going forward.
    await session.prompt({ role: "assistant", content: mathResult });

    // Return it as if that's what the assistant said to the user.
    return mathResult;
  }

  // The assistant didn't want to use the calculator. Just return its response.
  return result;
}

console.log(await promptWithCalculator("What is 2 + 2?"));

Multimodal inputs

All of the above examples have been of text prompts. Some language models also support other inputs. Our design initially includes the potential to support images and audio clips as inputs. This is done by using objects in the form { type: "image", content } and { type: "audio", content } instead of strings. The content values can be the following:

  • For image inputs: ImageBitmapSource, i.e. Blob, ImageData, ImageBitmap, VideoFrame, OffscreenCanvas, HTMLImageElement, SVGImageElement, HTMLCanvasElement, or HTMLVideoElement (will get the current frame). Also raw bytes via BufferSource (i.e. ArrayBuffer or typed arrays).

  • For audio inputs: for now, Blob, AudioBuffer, or raw bytes via BufferSource. Other possibilities we're investigating include HTMLAudioElement, AudioData, and MediaStream, but we're not yet sure if those are suitable to represent "clips": most other uses of them on the web platform are able to handle streaming data.

Sessions that will include these inputs need to be created using the expectedInputs option, to ensure that any necessary downloads are done as part of session creation, and that if the model is not capable of such multimodal prompts, the session creation fails. (See also the below discussion of expected input languages, not just expected input types.)

const session = await ai.languageModel.create({
  // { type: "text" } is not necessary to include explicitly, unless
  // you also want to include expected input languages for text.
  expectedInputs: [
    { type: "audio" },
    { type: "image" }
  ]
});

const referenceImage = await (await fetch("/reference-image.jpeg")).blob();
const userDrawnImage = document.querySelector("canvas");

const response1 = await session.prompt([
  "Give a helpful artistic critique of how well the second image matches the first:",
  { type: "image", content: referenceImage },
  { type: "image", content: userDrawnImage }
]);

console.log(response1);

const audioBlob = await captureMicrophoneInput({ seconds: 10 });

const response2 = await session.prompt([
  "My response to your critique:",
  { type: "audio", content: audioBlob }
]);

Future extensions may include more ambitious multimodal inputs, such as video clips, or realtime audio or video. (Realtime might require a different API design, more based around events or streams instead of messages.)

Details:

  • Cross-origin data that has not been exposed using the Access-Control-Allow-Origin header cannot be used with the prompt API, and will reject with a "SecurityError" DOMException. This applies to HTMLImageElement, SVGImageElement, HTMLVideoElement, HTMLCanvasElement, and OffscreenCanvas. Note that this is more strict than createImageBitmap(), which has a tainting mechanism which allows creating opaque image bitmaps from unexposed cross-origin resources. For the prompt API, such resources will just fail. This includes attempts to use cross-origin-tainted canvases.

  • Raw-bytes cases (Blob and BufferSource) will apply the appropriate sniffing rules (for images, for audio) and reject with a "NotSupportedError" DOMException if the format is not supported. This behavior is similar to that of createImageBitmap().

  • Animated images will be required to snapshot the first frame (like createImageBitmap()). In the future, animated image input may be supported via some separate opt-in, similar to video clip input. But we don't want interoperability problems from some implementations supporting animated images and some not, in the initial version.

  • For HTMLVideoElement, even a single frame might not yet be downloaded when the prompt API is called. In such cases, calling into the prompt API will force at least a single frame's worth of video to download. (The intent is to behave the same as createImageBitmap(videoEl).)

  • Text prompts can also be done via { type: "text", content: aString }, instead of just aString. This can be useful for generic code.

  • Attempting to supply an invalid combination, e.g. { type: "audio", content: anImageBitmap }, { type: "image", content: anAudioBuffer }, or { type: "text", content: anArrayBuffer }, will reject with a TypeError.

  • As described above, you can also supply a role value in these objects, so that the full form is { role, type, content }. However, for now, using any role besides the default "user" role with an image or audio prompt will reject with a "NotSupportedError" DOMException. (As we explore multimodal outputs, this restriction might be lifted in the future.)

Structured output or JSON output

To help with programmatic processing of language model responses, the prompt API supports structured outputs defined by a JSON schema.

 const session = await ai.languageModel.create();

const responseJSONSchemaObj = new AILanguageModelResponseSchema({
  type: "object",
  required: ["Rating"],
  additionalProperties: false,
  properties: {
    Rating: {
      type: "number",
      minimum: 0,
      maximum: 5,
    },
  },
});

// Prompt the model and wait for the json response to come back.
const result = await session.prompt("Summarize this feedback into a rating between 0-5: "+
  "The food was delicious, service was excellent, will recommend.",
  {responseJSONSchema : responseJSONSchemaObj}
);
console.log(result);

The responseJSONSchema option for prompt() and promptStreaming() can also accept a JSON schema directly as a JavaScript object. This is particularly useful for cases where the schema is not reused for other prompts.

While processing the JSON schema, in cases where the user agent detects unsupported schema a "NotSupportedError" DOMException, will be raised with appropriate error message. The result value returned is a string, that can be parsed with JSON.parse(). If the user agent is unable to produce a response that is compliant with the schema, a "SyntaxError" DOMException will be raised.

Configuration of per-session parameters

In addition to the systemPrompt and initialPrompts options shown above, the currently-configurable model parameters are temperature and top-K. The params() API gives the default and maximum values for these parameters.

 const customSession = await ai.languageModel.create({
  temperature: 0.8,
  topK: 10
});

const params = await ai.languageModel.params();
const conditionalSession = await ai.languageModel.create({
  temperature: isCreativeTask ? params.defaultTemperature * 1.1 : params.defaultTemperature * 0.8,
  topK: isGeneratingIdeas ? params.maxTopK : params.defaultTopK
});

https://github.com/webmachinelearning/prompt-api


Wednesday, February 12, 2025

Local Translation API in Chrome-based Browsers

Client-side Translator API with a model built into Chrome (from version 131).

Possible use case: customer support chat which allows for users to type in their first language and receive real-time translation for the support agent. github.com/webmachinelearning/translation-api

The Translator API has two important methods:

  • canTranslate(): Checks if a translation model for your language pair is ready. Returns "readily" if the model is already available on device, "after-download" if the browser first needs to download the model, and "no" if translation is not possible.
  • createTranslator(): This sets up your Translator object asynchronously. If the model needs downloading, it'll wait until it's ready.

The Translator object has just one method:

  • translate(): Feed it the source text, and it outputs the translated version.

As this is experimental and Chrome-specific for now, be sure to wrap all your code in feature detection.

const supportsOnDevice = 'model' in window && 'createTranslator' in model;
if (!supportsOnDevice) {
  return;
}

const parameters = { sourceLanguage: 'en', targetLanguage: 'pt' };
const modelState = await model.canTranslate(parameters);
if (modelState === 'no') {
  return;
}
const onDeviceTranslator = await model.createTranslator(parameters);

const result = await onDeviceTranslator.translate(input);
if (!result) {
  throw new Error('Failed to translate');
}
return result;

The model needs time to become available to the user. You can approach this in two ways:

  • Wait to enable your translation-powered UI elements once the model is ready.
  • Start with server-side AI for translation, then switch to client-side once the model has downloaded.

Sign up for the Translator API origin trial to enable your translation features for all users on your origin, on Chrome. Opening an Issue on the Explainer.

Use the Translator API in Chrome to translate text in the browser, using local AI models.

Translation of content on the web has typically required using a cloud service. First, the source content is uploaded to a server, which runs the translation to a target language, then the resulting text is downloaded and returned to the user. By running translation on the client, you save the time required by server trips and the cost of hosting the translation service.

Join the Translator API origin trial, running in Chrome beginning with version 131 (Chrome and derivative branches like Dev, Canary).

While you always know the target language for translations, you may not always know the source language, such as in user-generated content. For such cases, the Translator API proposal includes both the Translator API and the Language Detector API, also available in an origin trial. Sign up for both origin trials to use these APIs together.

To start using the Translator API, follow these steps:

  1. Acknowledge Google's Generative AI Prohibited Uses Policy.
  2. Go to the Translator API origin trial.
  3. Click Register and fill out the form.
    • In the Web origin field, provide your origin or extension ID, chrome-extension://YOUR_EXTENSION_ID.
  4. To submit, click Register.
  5. Copy the token provided, and add it to every web page on your origin or file for your Extension, on which you want the trial to be enabled.
  6. Start using the Translator API.

Learn more about how to get started with origin trials.

To access the Translator API on localhost during the origin trial, you must update Chrome to the latest version. Then, follow these steps:

  1. Go to chrome://flags/#translation-api.
  2. Select Enabled.
    • To try more language pairs, select Enabled without language pack limit.
  3. Click Relaunch or restart Chrome.

To determine if the Translator API is supported, run the following feature detection snippet.

if ('ai' in self && 'translator' in self.ai) {
  // The Translator API is supported.
}

Translation is managed with language packs, downloaded on demand. A language pack is like a dictionary for a given language.

  • sourceLanguage: The current language for the text.
  • targetLanguage: The final language the text should be translated into.

Use BCP 47 language short codes as strings. For example, 'es' for Spanish or 'fr' for French.

 const translatorCapabilities = await self.ai.translator.capabilities();
 translatorCapabilities.languagePairAvailable('es', 'fr');
 // 'readily'

The languagePairAvailable() function can return any of the following results:

  • no: It's not possible for this browser to translate as requested.
  • readily: The browser can translate as requested.
  • after-download: The browser can perform the translation, but only after it downloads the relevant model or language packs.

You can listen for model download progress using the downloadprogress event:

const translator = await self.ai.translator.create({
  sourceLanguage: 'es',
  targetLanguage: 'fr',
  monitor(m) {
    m.addEventListener('downloadprogress', (e) => {
      console.log(`Downloaded ${e.loaded} of ${e.total} bytes.`);
    });
  },
});

If the download fails, then downloadprogress events stop being emitted and the ready promise is rejected.

To create a translator, call the asynchronous translation.createTranslator() function. Like canTranslate(), it requires an options parameter with two fields, one for the sourceLanguage and one for the targetLanguage.

// Create a translator that translates from English to French.
const translator = await self.ai.translator.create({
  sourceLanguage: 'en',
  targetLanguage: 'fr',
});

Once you have a translator, call the asynchronous translate() function to translate your text.

await translator.translate('Where is the next bus stop, please?');
// "Où est le prochain arrêt de bus, s'il vous plaît ?"

The following limitations apply during the origin trial.

At this time, up to three language packs can be downloaded for translation. We're committed to expand the range of supported languages in future releases, while maintaining high standards for user privacy. You can confirm if the language pair you need is supported with the languagePairAvailable() function.

It's possible that certain, less frequently used language pairs may be used for fingerprinting. For example, it's more common to translate between English and Spanish than between less common languages, such as Gaelic and Catalan. A less common language pair could be considered a data point for user identification.

During the origin trial, we're limiting the potential translatable language pairs to protect user privacy. Language pairs must meet the following criteria:

  • Both the source and the destination language are set as preferred languages in Chrome.
  • Or, one of he languages is set as a preferred language in Chrome, and the other is among the following popular languages:
    • English (en)
    • Mandarin Chinese (zh; simplified) or Taiwanese Mandarin (zh-Hant; traditional)
    • Japanese (ja)
    • Portuguese (pt)
    • Russian (ru)
    • Spanish (es)
    • Turkish (tr)
    • Hindi (hi)
    • Vietnamese (vi)
    • Bengali (bn)

For local prototyping, you can bypass these checks by running Chrome with the command line option --disable-features=TranslationAPIAcceptLanguagesCheck. Alternatively, set chrome://flags/#translation-api to Enable without language pack limit.

Visit chrome://on-device-translation-internals/ to manually install and uninstall language packs.

Translations are processed sequentially. If you send large amounts of text to be translated, subsequent translations are blocked until the earlier ones complete.

For the best responsiveness of your translation requests, chunk them together and consider displaying a loading interface, such as a spinner, to convey that a translation is ongoing.

During the origin trial, the Translator API is only supported from the main thread. We intend to support it in web workers once the API is widely available.

You can see the Translator API, used in combination with the Language Detector API, in the Translator and Language Detector API playground.

We're working to standardize the Translator API, to ensure cross-browser compatibility.

Our API proposal received community support and has moved to the W3C Web Incubator Community Group for further discussion. The Chrome team requested feedback from the W3C Technical Architecture Group and asked Mozilla and WebKit for their standards positions.

Start testing the Translator API now by joining the origin trial and share your feedback. Your input can directly impact how we build and implement future versions of this API, and all built-in AI APIs.

  • Install Translation Detection API on Chrome

  • Go to chrome://flags/#language-detection-api.
  • Select Enabled
  • Go to chrome://flags/#translation-api.
  • Select Enabled without language pack limit to try more language pairs.
  • Click Relaunch or restart Chrome.
  • Open a new tab, go to chrome://components.
  • Find Chrome TranslateKit
  • Click "Check for update" button to download the language model. The version number should update.
  • (Optional) Open a new tab, go to chrome://on-device-translation-internals/
  • (Optional) Install language pairs.


Tuesday, January 7, 2025

OpenAI-compatible API with FastAPI

# source: https://towardsdatascience.com

import asyncio
import json
import time

from typing import Optional, List

from pydantic import BaseModel, Field

from starlette.responses import StreamingResponse
from fastapi import FastAPI, HTTPException, Request

app = FastAPI(title="OpenAI-compatible API")


# data models
class Message(BaseModel):
    role: str
    content: str


class ChatCompletionRequest(BaseModel):
    model: Optional[str] = "mock-gpt-model"
    messages: List[Message]
    max_tokens: Optional[int] = 512
    temperature: Optional[float] = 0.1
    stream: Optional[bool] = False


async def _resp_async_generator(text_resp: str):
    # let's pretend every word is a token and return it over time
    tokens = text_resp.split(" ")

    for i, token in enumerate(tokens):
        chunk = {
            "id": i,
            "object": "chat.completion.chunk",
            "created": time.time(),
            "model": request.model,
            "choices": [{"delta": {"content": token + " "}}],
        }
        yield f"data: {json.dumps(chunk)}\n\n"
        await asyncio.sleep(1)
    yield "data: [DONE]\n\n"


@app.post("/chat/completions")
async def chat_completions(request: ChatCompletionRequest):
    if request.messages:
        resp_content = (
            "As a mock AI Assitant, I can only echo your last message: "
            + request.messages[-1].content
        )
    else:
        resp_content = "As a mock AI Assitant, I can only echo your last message, but there wasn't one!"
    if request.stream:
        return StreamingResponse(
            _resp_async_generator(resp_content), media_type="application/x-ndjson"
        )

    return {
        "id": "1337",
        "object": "chat.completion",
        "created": time.time(),
        "model": request.model,
        "choices": [{"message": Message(role="assistant", content=resp_content)}],
    }


if __name__ == "__main__":
    import uvicorn

    uvicorn.run(app, host="0.0.0.0", port=8000)


# Direct generation
from openai import OpenAI

# init client and connect to localhost server
client = OpenAI(
    api_key="fake-api-key",
    base_url="http://localhost:8000" # change the default port if needed
)

# call API
chat_completion = client.chat.completions.create(
    messages=[
        {
            "role": "user",
            "content": "Say this is a test",
        }
    ],
    model="gpt-1337-turbo-pro-max",
)

# print the top "choice"
print(chat_completion.choices[0].message.content)

# Streaming chunks
from openai import OpenAI

# init client and connect to localhost server
client = OpenAI(
    api_key="fake-api-key",
    base_url="http://localhost:8000" # change the default port if needed
)

stream = client.chat.completions.create(
    model="mock-gpt-model",
    messages=[{"role": "user", "content": "Say this is a test"}],
    stream=True,
)
for chunk in stream:
    print(chunk.choices[0].delta.content or "")

Wednesday, November 20, 2024

Python code for portalquery.just.ro/CautareDosare API

import requests
import xml.dom.minidom
# http://portalquery.just.ro/query.asmx?WSDL
# http://portalquery.just.ro/query.asmx
# https://portal.just.ro/SitePages/acces.aspx

url = "http://portalquery.just.ro/query.asmx"

payload = """<?xml version="1.0" encoding="utf-8"?>
<soap12:Envelope
    xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
    xmlns:xsd="http://www.w3.org/2001/XMLSchema"
    xmlns:soap12="http://www.w3.org/2003/05/soap-envelope">
    <soap12:Body>
        <CautareDosare2
            xmlns="portalquery.just.ro">
            <numarDosar>1268/2/2022</numarDosar>
            <obiectDosar></obiectDosar>
            <numeParte></numeParte>
            <institutie>CurteadeApelBUCURESTI</institutie>
            <dataStart>2022-01-01</dataStart>
            <dataStop>2024-01-01</dataStop>
            <dataUltimaModificareStart>2022-01-01</dataUltimaModificareStart>
            <dataUltimaModificareStop>2024-01-01</dataUltimaModificareStop>
        </CautareDosare2>
    </soap12:Body>
</soap12:Envelope>"""
headers = {
'Content-Type': 'application/soap+xml; charset=utf-8',
'SOAPAction': 'portalquery.just.ro/CautareDosare2'
}

response = requests.request("POST", url, headers=headers, data=payload)

dom = xml.dom.minidom.parseString(response.text)
pretty_xml_as_string = dom.toprettyxml()
print(pretty_xml_as_string)


url = "http://portalquery.just.ro/query.asmx"

payload = """<?xml version="1.0" encoding="utf-8"?>
<soap:Envelope
    xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
    xmlns:xsd="http://www.w3.org/2001/XMLSchema"
    xmlns:soap="http://www.w3.org/2003/05/soap-envelope">
    <soap:Body>
        <CautareDosare
            xmlns="portalquery.just.ro">
            <numarDosar>1269/2/2022</numarDosar>
            <obiectDosar></obiectDosar>
            <numeParte></numeParte>
            <institutie>CurteadeApelBUCURESTI</institutie>
            <dataStart>2022-01-01</dataStart>
            <dataStop>2024-01-01</dataStop>
            <dataUltimaModificareStart>2022-01-01</dataUltimaModificareStart>
            <dataUltimaModificareStop>2024-01-01</dataUltimaModificareStop>
        </CautareDosare>
    </soap:Body>
</soap:Envelope>"""
headers = {
'Content-Type': 'application/soap+xml; charset=utf-8',
'SOAPAction': 'portalquery.just.ro/CautareDosare'
}

response = requests.request("POST", url, headers=headers, data=payload)

dom = xml.dom.minidom.parseString(response.text)
pretty_xml_as_string = dom.toprettyxml()
print(pretty_xml_as_string)

'''
Serviciul web portal.just.ro permite accesul la datele despre dosare, părţi şi şedinţe de judecată.
Adresa serviciului web este: http://portalquery.just.ro/query.asmx

    Serviciul web permite accesul la date folosind două metode de interogare:
    - căutare dosare
    - căutare şedinţe

 
Căutarea dosarelor
 
Căutarea dosarelor se face după următorii parametri de interogare:
- număr dosar
- obiect dosar
- nume parte
- instanţă
- perioadă (dosare dintr-un interval de timp)
 
La o interogare se pot folosi combinaţii de parametri. Se va completa obligatoriu cel puţiu unul din parametrii: număr dosar, obiect dosar, nume parte.
Notă: lista rezultată la o interogare va conţine maxim 1000 dosare.
 
Informaţiile obţinute sunt:
- numărul dosarului (format numar unic)
- număr în format vechi (dacă există)
- data dosarului
- instanţa dosarului
- departamentul (secţia)
- categoria cazului
- stadiul procesual al dosarului
- lista de parţi din dosar
- lista de termene ale dosarului
- lista de căi de atac

Căutarea şedinţelor
 
Căutarea şedinţelor se face după următorii parametri de interogare:
- data şedinţă (obligatoriu)
- instanţa (obligatoriu)
 
Informaţiile obţinute sunt:
- departamentul (secţia)
- numele completului de judecată
- data şedinţei
- ora şedinţei
- lista de dosare din şedinţă
 
Serviciul Web a fost creat folosind platforma .NET 3.5 şi ASP.NET. Astfel, cei care utilizează aceste servicii folosind .NET se vor putea integra uşor. Totuşi, nu ar trebui să fie nici o dificultate pentru apelul acestor servicii folosind orice altă platformă de dezvoltare software (PHP, Java, etc.).
 
Documentaţia detaliată a serviciului poate fi consultată accesând documentul:

 Documentarea serviciului web de conectare programatică la date şi export.docDocumentarea serviciului web de conectare programatică la date şi export.doc
'''